Asset Ownership Mapping: How to Route Every Vulnerability to the Right Owner Automatically
Findings stall when nobody knows who owns the asset, so automated asset ownership mapping turns tags, CMDB records, and code owners into routing decisions.


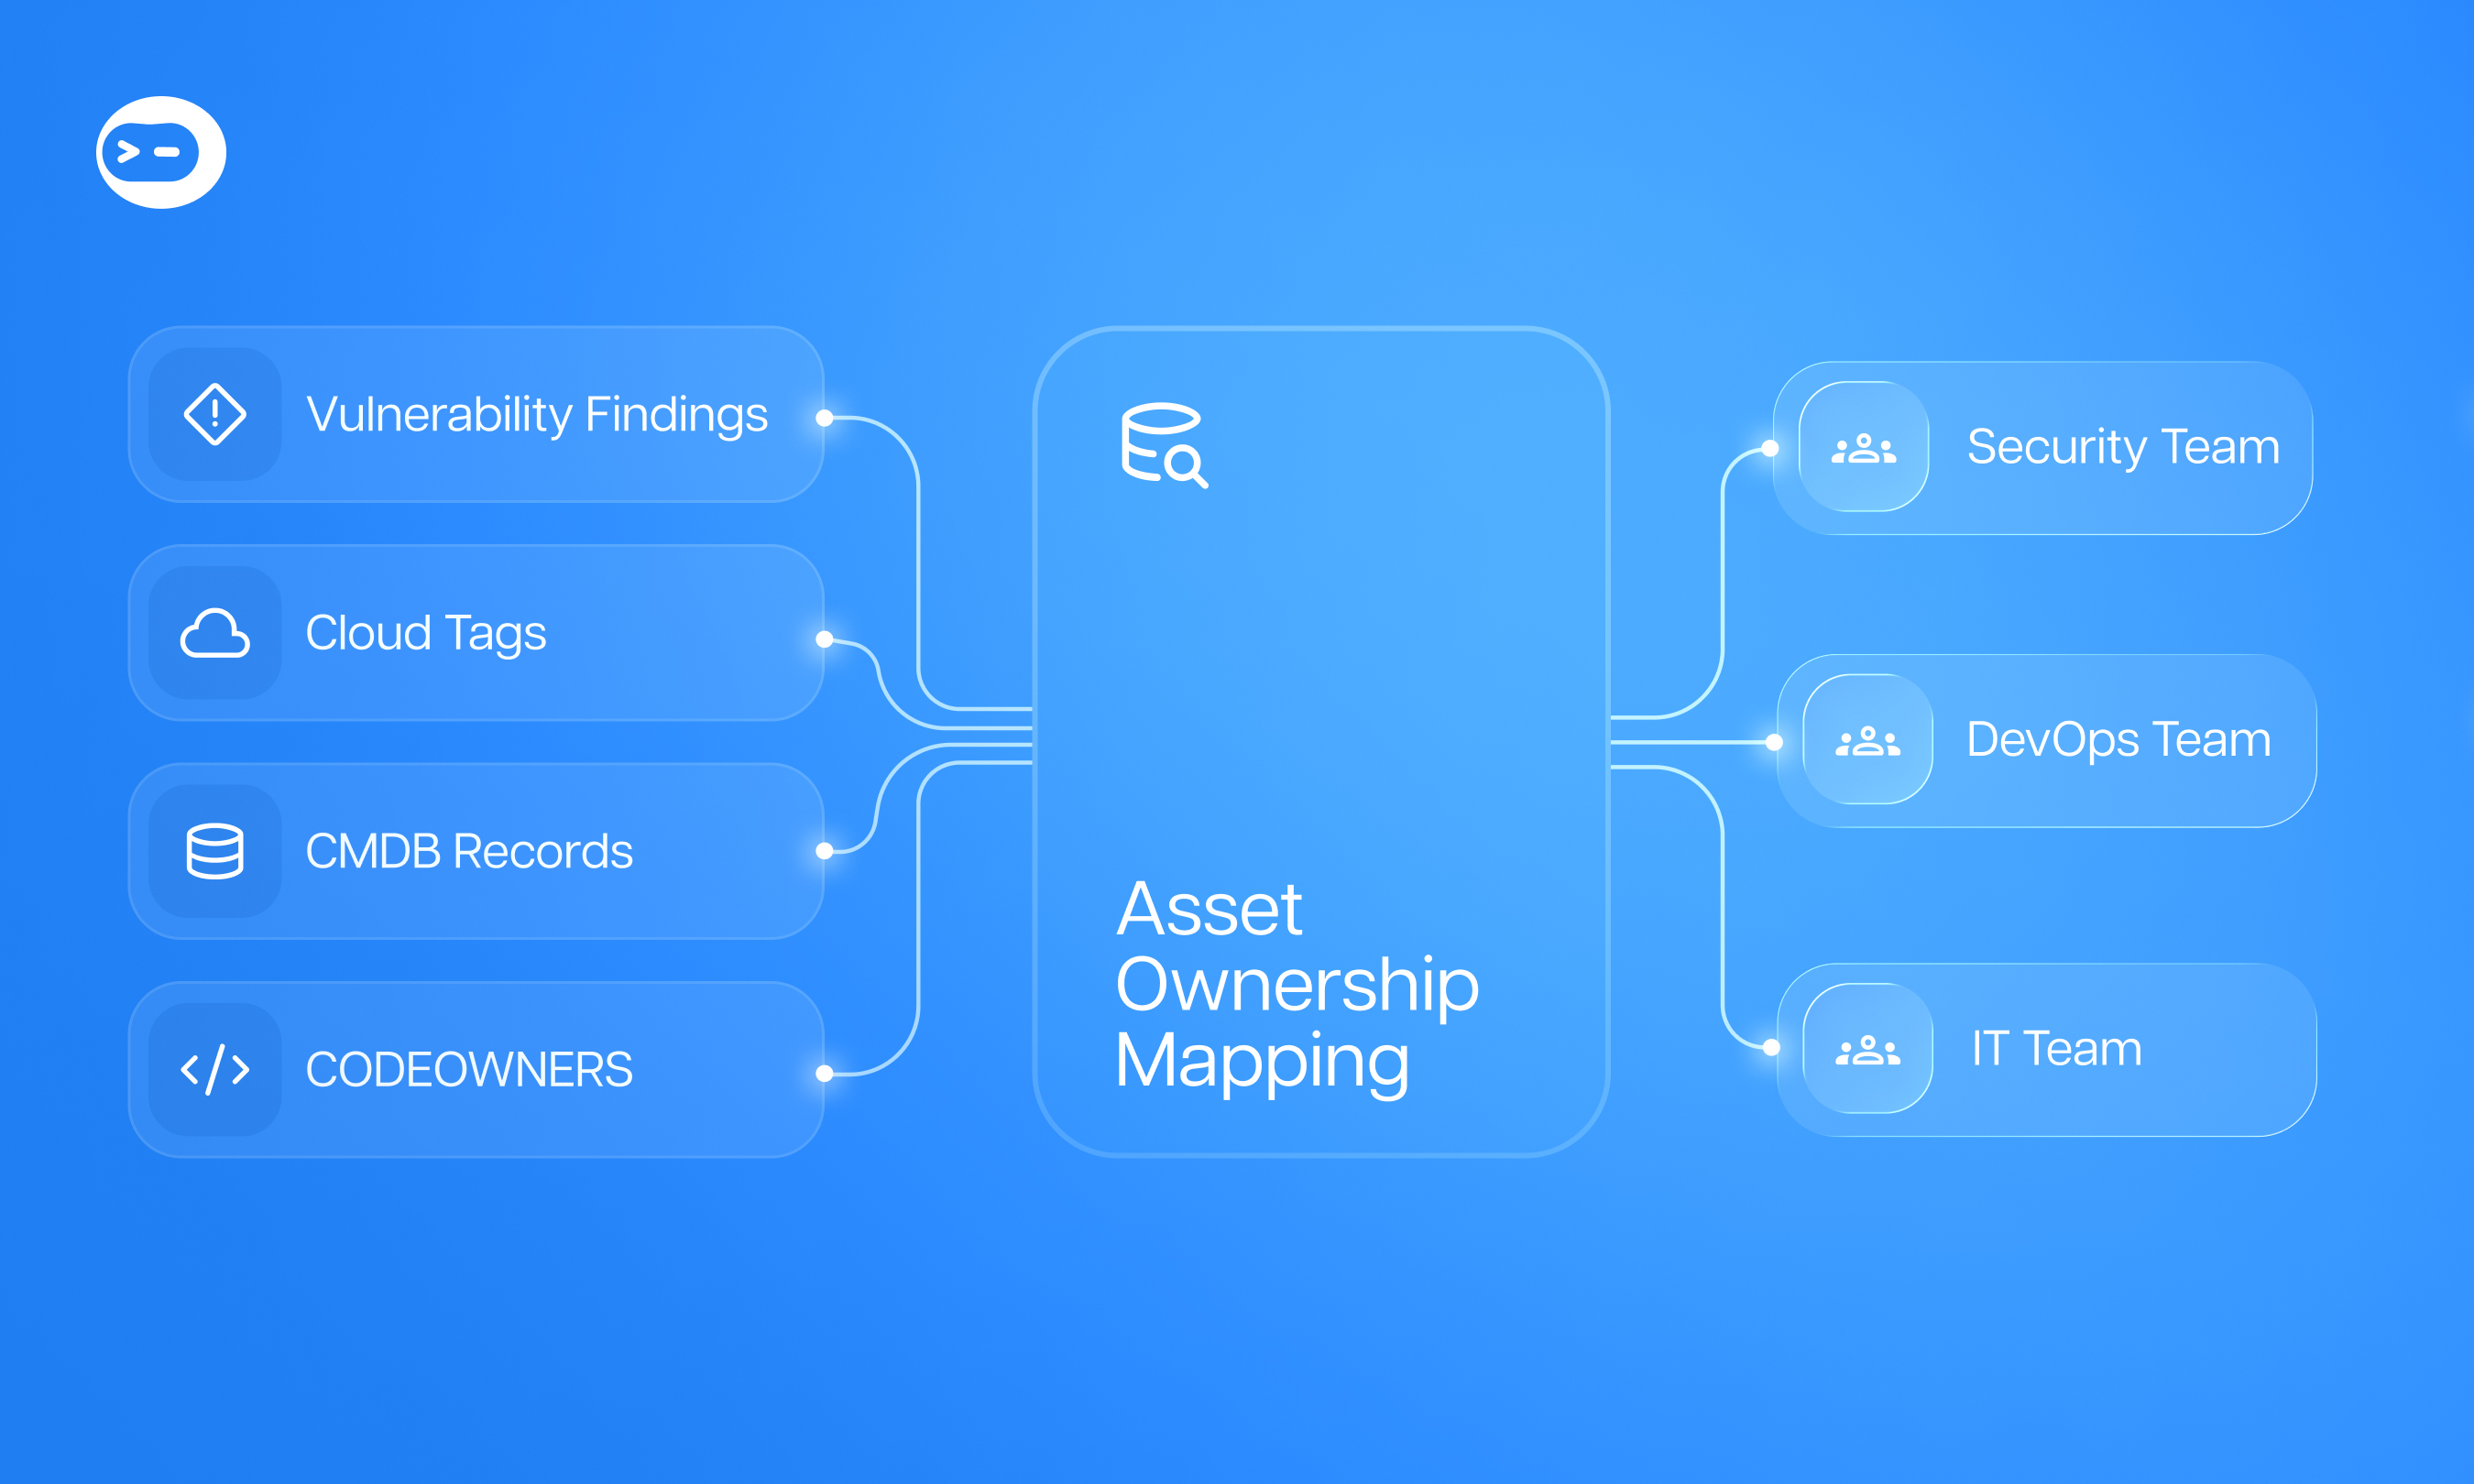
Asset ownership mapping is a maintained link between every asset and the team accountable for fixing it, plus a confidence score for that link. It draws on signals like cloud tags, CMDB records, code owners, and identity data. Automated, the map routes each vulnerability finding to the correct resolver group with context and an SLA instead of a shared queue.
Key Takeaways
- In BlinkOps’ work with VM teams, asset ownership is the step many still resolve by hand, one finding at a time.
- Exploitation was the top initial access vector in Verizon’s 2026 DBIR dataset, so routing delay is exposure time.
- No single ownership source is reliable. Correlate cloud tags, CMDB records, CODEOWNERS files, and identity data.
- Score each mapping’s confidence and send uncertain ones to a human, whose decision updates the inventory.
- Tie every owner to a case and an exposure-based SLA, then verify the fix with a rescan.
- Agents add capacity to the team you have, while the platform harness, approvals, and audit trail keep control.
What Is Asset Ownership Mapping?
Asset ownership mapping is a maintained link between each asset and its resolver group, plus a record of how confident you are in that link. The resolver group is the team or person who can ship the fix. Without that link, a vulnerability finding is a fact with nowhere to go.
Most estates already hold ownership signals. Cloud tags are key-value metadata, and categories like Team, Department, and Project show who claimed a resource at deploy time. The earlier your organization can align on a tagging strategy, the less clean-up work you’ll need to do later.
Standards treat ownership as part of the inventory. CIS Controls v8.1 Safeguard 1.1 expects the inventory to record the enterprise asset owner and department for each asset, cloud assets included. The NIST Cybersecurity Framework 2.0 calls for maintained inventories of hardware, software, services, and systems under ID.AM, without prescribing an owner field.
Asset ownership is the operational layer between a finding and a fix. Scanners report what is wrong. The map tells you who changes it.
Why Do Vulnerabilities Stall Without Clear Ownership?
Ask a vulnerability management team about its week and the routine is familiar. Pull findings from several scanners, decide which ones matter, work out who owns the affected asset, open tickets, then chase. In BlinkOps’ work with VM teams, the ownership step is where remediation slows, especially on shared infrastructure that several teams touch.
That observation comes from practitioners rather than a published study. The cost of slow remediation, however, is well documented.
In Verizon’s 2026 Data Breach Investigations Report, exploitation reached 31% of breaches with a known initial access vector, up from 20% the prior year. That made it the top initial access vector in Verizon’s dataset. Among contributing organizations, only 26% of CISA Known Exploited Vulnerabilities were fully remediated, with a median of 43 days to full remediation.
The Edgescan 2026 Vulnerability Statistics Report found that among Edgescan customers with 1,000+ employees, 37% of vulnerabilities discovered in a 12-month period remained unresolved. In that 2025 data, average high and critical MTTR was 54.81 days for applications and APIs and 39 days for devices and networks.
For federal civilian agencies, CISA’s Binding Operational Directive 26-04 ties remediation timelines to asset context such as public exposure. Private companies aren’t bound by it, but the logic carries over: if you don’t know the asset, you can’t know which clock applies.
For a SecOps leader, this lands on SLA attainment. Every finding parked in a shared queue burns SLA time before anyone starts the fix. Adding analysts to chase owners doesn’t scale at flat headcount, and hand-built routing rules drift into the maintenance trap.
Which Signals Reveal Who Owns an Asset?
No single source answers the asset ownership question reliably. Strong programs correlate four signals and weigh them against each other.
Cloud Resource Tags
Tags are the fastest signal because they already exist. Team, Department, and Project tags point to an owner, while Environment tags help classify exposure. CISA’s BOD 26-04 guidance likewise recommends consistently tagging assets with environment, exposure status, and asset type. When a cloud policy requires tags at deploy time, it can block users from deploying resources that are missing those tags.
Tags are also typically unvalidated free text, and a tag can name a team that was renamed last quarter. Resources deployed prior to those policies being established can carry no tags at all. Those untagged assets become orphaned assets.
CMDB and Asset Inventory Records
The CMDB usually holds the formal owner, business service, and support group. It is the closest match to the record CIS Safeguard 1.1 describes. Its weakness is freshness, because records lag behind cloud resources that spin up and down daily.
Code Ownership (CODEOWNERS)
For application findings, repositories carry their own ownership data. According to GitHub’s CODEOWNERS documentation, code owners are automatically requested for review on pull requests that modify code they own. That maps code paths to teams, though it doesn’t map a deployed cloud asset to an owner on its own.
Identity and Org Data
Identity provider and HR data confirm whether the named owner still works at the company and which team they belong to now. This signal catches a common silent failure: a correct-looking owner who has left.
How Do You Automate Ownership Routing for Vulnerabilities?
Automated vulnerability routing works best as a staged workflow. Deterministic steps handle the repeatable parts, agents handle the judgment calls, and humans decide where confidence runs out. Blink offers pre-built ownership routing agents for this workflow.
- Ingest every finding. Pull findings from each scanner you run, such as Tenable, Qualys, Wiz, or Rapid7, into one queue.
- Resolve the asset. Match each finding to a single asset record across scanner and inventory feeds, removing duplicates before routing.
- Correlate signals and score confidence. Normalize ownership values first, then weigh tags, CMDB, CODEOWNERS, and identity data into one confidence score.
- Route high-confidence mappings. Open a case for the resolver group with context and a suggested fix, synced to ITSM and Slack or Teams.
- Send low-confidence mappings to a human. A reviewer confirms or corrects the owner in chat, and the decision writes back to the inventory.
- Start an exposure-based SLA timer. Set the deadline by exposure and severity, and escalate overdue items to a manager or backup queue.
- Verify the fix. Rescan after the change lands, close the case only when the finding is gone, and reopen it if still reachable.
Step 3 carries forward an old tagging rule: stick to standard naming conventions to help enforce consistency. If “secops,” “SecOps,” and “Security-Ops” resolve to three teams, findings land in queues nobody watches. Normalizing ownership values before routing on them prevents that.
Step 5 reframes another familiar idea. Tagging teams once used Slack to add tags with approval, and the same pattern now confirms asset ownership. Each proposed owner carries its evidence, its confidence score, and a record of who approved it.
For the SecOps leader, the payoff is capacity, not headcount. Analysts spend less time acting as a routing desk and more time on the findings that need their expertise.
What Happens When an Asset Has No Owner?
Some assets fail every signal. A test VM with no tags, no CMDB record, and a departed creator is still exposed. Orphaned assets need a defined path, or they become the findings nobody closes.
A practical orphan policy has four parts:
- Default owner. Assign a fallback queue by environment or cloud account, so every finding has a starting point.
- Time-boxed claim. Give the likely team a fixed window to claim or reject the asset before escalation.
- Escalation path. Move unclaimed assets to the account owner or platform team, with the SLA clock still running.
- Exception record. Log accepted risk with a justification and an expiry date, then recheck it when that date arrives.
Self-service forms close the loop. Owners can claim, contest, or hand off an asset without leaving their tools, and each answer updates the map. BlinkOps describes a similar exception pattern in its post on running one case per host, where exceptions carry expiration dates and reminders.
Where Blink Fits
BlinkOps built its agentic vulnerability management platform on Blink for teams handling findings across many scanners and clouds. Pre-built micro agents cover prioritization, ownership routing, hardening, and verification, and teams can build their own. Agents work from your asset inventory, owners, and environment tags, so the right finding reaches the right team without manual triage.
The building blocks around the agents matter as much. Tables hold asset inventory, ownership, exceptions, and every scanner finding in one place the agents query.
Built-in security case management tracks every remediation, and dashboards show live exposure by asset, owner, and SLA. Interactive agents reach owners in Slack or Teams with the finding and the fix.
When no patch exists yet, agents generate compensating controls so teams can harden while patches wait. Blink stays vendor-neutral across Tenable, Qualys, Wiz, Axonius, Rapid7, and 30,000+ integrations.
Control lives in the platform harness, not in a prompt. Every action is an ability you granted, scoped per action and per use case, and irreversible actions wait for approval by default. Every change lands in an audit trail, and you can see how BlinkOps bounds agent actions in detail.
The foundation matters in practice. Consolidating scanner and asset feeds into one deduplicated inventory gives ownership routing a clean base to work from.
Conclusion: Automate the Map, Verify the Close
Findings don’t fix themselves. Owners do. Remediation starts with knowing who owns each asset, with evidence to back up that answer.
Build the asset ownership map from several signals, normalize them, and score confidence. Let deterministic workflows route the clear cases, and keep humans on the uncertain ones. Tie every owner to a case and an exposure-based SLA, then close the loop with a verified rescan.
That’s how a SecOps team protects SLA attainment at flat headcount, with every routing decision on the record.
Request a demo of the BlinkOps agentic security operations platform.
FAQ: Asset Ownership and Vulnerability Routing
What Does Asset Ownership Mean in Vulnerability Management?
Asset ownership means a named team or person is accountable for remediating vulnerabilities on a specific asset. That owner is the resolver group that receives the finding, carries the SLA, and confirms the fix. CIS Safeguard 1.1 treats owner and department as standard inventory fields.
Are Cloud Tags Enough to Establish Asset Ownership?
Tags are a strong starting signal, but rarely enough alone. They are typically unvalidated, they go stale when teams reorganize, and older resources often lack them. Cross-check tags against CMDB records, code ownership, and identity data before routing on them.
How Should You Handle Low-Confidence Ownership Mappings?
Route them to a human reviewer instead of guessing. Show the competing signals and the proposed owner, and let the reviewer confirm or correct it in chat or a form. Write the decision back to the inventory and the audit trail, so the next finding on that asset routes with confidence.
How Does Ownership Routing Connect to Remediation SLAs?
An SLA only works when someone owns the clock. Routing assigns the owner, and exposure context sets the deadline. Federal agencies already work this way under BOD 26-04, where public exposure shapes remediation timelines.
For everyone else, an owner tied to a case makes SLA attainment measurable. Escalation then runs on rules instead of reminders.


Related: